Mark Cuban's useful proposition is that generic software forces a business to adapt to the tool, while custom AI can adapt the tool to the business. The proposition is directionally right. The common implementation is not.
Fine-tuning is not “put all our files into a model.” It is not a replacement for a database, a search system, permissions, or management judgment. It is a way to make a model repeat stable behavior: the voice, format, classification logic, escalation pattern, and decision structure that distinguish how your company works.
The facts that change belong in retrieval. The behavior that should remain consistent can belong in an adapter. Actions belong behind explicit tools and permissions. Quality belongs in a test set. Accountability belongs to a named human.
The opportunity is not to build one giant company brain. It is to build a small, measured operating system for one recurring job.
The shortest honest answer
- Choose one narrow, frequent, expensive workflow.
- Prove what prompting, rules, retrieval, and structured outputs can already do.
- Fine-tune only the stable behavior that the baseline still performs inconsistently.
- Keep current facts and source citations outside the weights.
- Integrate the result where people already work, with permission limits and human review.
- Measure corrections, time saved, defects prevented, and unsupported promises.
01 / Diagnose
Decide the job before you touch a model
Start with a job description, not a technology preference. A useful first sentence has three parts:
When this event happens, the system should produce this result, under these constraints.
For example: “When a residential cabinet inquiry arrives, draft an estimate request in our tone, extract the job details into the CRM schema, identify missing measurements, and refuse to promise an installation date.”
That sentence is trainable and testable. “Build an AI that knows the business” is neither.
Ticket or email triage
Classify intent, urgency, owner, and next action the way your strongest operator would. The input and output are visible, frequent, and easy to audit.
Structured extraction
Turn invoices, quotes, applications, or field notes into a fixed schema. Test structured output before fine-tuning. Train only if document-specific interpretation remains inconsistent.
Drafting within policy
Create estimates, follow-ups, or support replies using a stable voice and decision sequence. A human approves the message until the measured error rate is acceptable.
Know everything
A universal business assistant hides scope, permissions, data quality, and failure costs. Break it into separate specialists with separate evaluations.
Use the lightest tool that solves the failure
Small businesses lose time when every AI problem is called “fine-tuning.” The actual choice is a routing problem.
| Observed failure | First intervention | Why | Fine-tune? |
|---|---|---|---|
| The answer is current but badly phrased | Prompt and examples | The knowledge exists. The instruction is weak. | Only if style remains inconsistent across many cases |
| The answer lacks a current price, policy, or order status | Retrieval or tool call | Changing facts should remain editable and traceable. | No, not for freshness |
| The output will not stay inside a schema | Structured outputs and validation | A schema is enforced by software, not prose. | Only for persistent interpretation errors |
| The model classifies or decides differently than the best employee | Few-shot baseline, then fine-tuning | The missing asset is a stable learned pattern. | Often |
| The system must update a CRM, send a message, or issue a refund | Tool integration and permissions | Actions need authorization, idempotency, logs, and limits. | Fine-tuning does not grant safe authority |
| The process itself is vague or contested | Fix the process | A model cannot stabilize a policy the company has not decided. | Not yet |
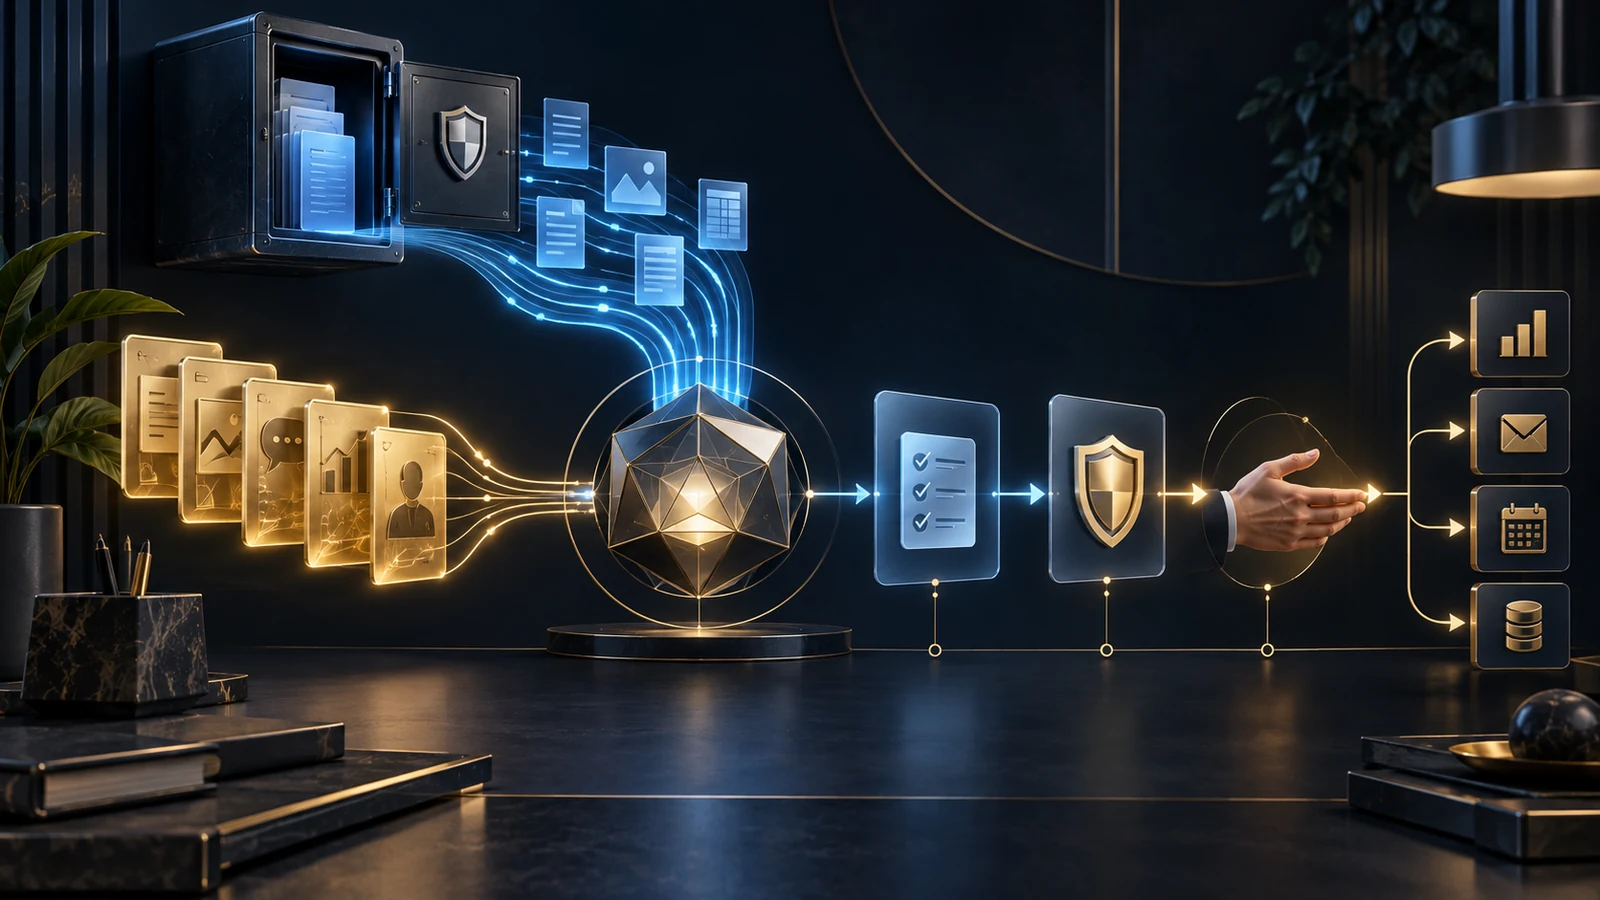
A ticket, form, invoice, call note, or task enters the workflow.
Current policies, prices, records, and cited sources are fetched.
The model follows the trained format, voice, and decision pattern.
Schemas, business rules, permissions, and evaluations check the result.
A human or bounded policy authorizes the external action.
02 / Specify
Write an acceptance contract
Before collecting training data, define what counts as correct. This is the difference between a demonstration and an operating system.
An acceptance contract for a support-drafting model might say:
- Uses the approved greeting and closing.
- Identifies the correct policy class.
- Never invents a price, date, status, or guarantee.
- Cites the retrieved policy identifier when required.
- Escalates complaints, refunds above a threshold, safety issues, and uncertain cases.
- Returns valid JSON for the helpdesk fields.
- Completes within the latency and cost budget.
Add a cost of failure. A wrong internal category can be corrected cheaply. An invented delivery promise can damage trust. A wrong medical, legal, financial, employment, or safety decision can cause serious harm. The more consequential the output, the more the system should retrieve sources, constrain actions, log decisions, and require qualified human review.
03 / Curate
Build a golden set, not a data dump
Your historical archive contains examples of the company at its best, average, confused, rushed, outdated, and wrong. Training on all of it teaches the model to reproduce the entire distribution.
Start with a screening set of roughly 100 to 300 high-quality examples for one task, plus 30 to 50 untouched evaluation cases. These are starting ranges, not laws. The right volume depends on task diversity, model quality, response length, and the precision you need.
Good source material
- Resolved support threads whose answers you would send again.
- Closed sales conversations with a clear, ethical next action.
- Approved estimates, proposals, and reports.
- Documents paired with the correct extracted fields.
- SOP situations paired with the action an experienced operator took.
- Human corrections that explain exactly why a draft was wrong.
What to exclude
- Unresolved threads with no authoritative outcome.
- Deprecated prices, policies, products, or promises.
- Junior answers that were never reviewed.
- Private data that is not necessary for the learned behavior.
- Documents you lack the right to use for training.
- Machine-generated examples that no knowledgeable person inspected.
Minimize before you anonymize
Anonymization is not a magic eraser. Names can be removed while combinations of location, order details, dates, and circumstances still identify a person. Begin by asking whether each field is necessary. Remove what the task does not need. Then replace identifiers with consistent placeholders such as [CUSTOMER], [EMAIL], [ORDER_ID], and [LOCATION].
Keep a written data register: source, owner, permitted use, sensitivity, retention period, access group, and deletion method. If the dataset contains regulated, contractual, employee, health, payment, or customer information, obtain appropriate legal and security review before training.
Represent the behavior explicitly
For conversational tasks, a message-based JSONL format makes the instruction, input, and ideal answer visible. Hugging Face TRL's SFT Trainer supports conversational datasets using a messages field.
{"messages":[
  {"role":"system","content":"You draft cabinet estimates. Follow current shop policy from retrieved context. Never invent lead times."},
  {"role":"user","content":"[CUSTOMER] wants twelve painted shaker doors. Measurements are incomplete. Asked whether installation can happen next Friday."},
  {"role":"assistant","content":"Thanks for the details. Before I can price or schedule the work, I need the finished opening width and height for all twelve doors. I cannot confirm next Friday until measurements are verified and the current production calendar is checked. I have listed the missing measurements below."}
]}
Do not train current lead times into the response. Train the behavior of checking, qualifying, and refusing to invent. Retrieve the actual calendar at run time.
Split by source, customer, or time
A random 80/10/10 split is easy to understand, but it can leak near-duplicate threads across train and test. When possible, split by customer, project, document family, or time period. Preserve a truly untouched test set. Otherwise the score may measure memorization of a template rather than generalization to new work.
04 / Baseline
Make the generic model earn the fine-tune
Before training, run the same evaluation against the strongest practical baseline:
- A clear system instruction.
- Three to ten representative examples.
- Retrieved current documents or records.
- A required output schema.
- Deterministic business-rule checks after generation.
Record every failure by category. If the baseline misses facts, fix retrieval. If it violates the schema, strengthen validation. If it misunderstands the task, improve the instruction and examples. Fine-tune when a stable pattern remains unreliable after these simpler controls.
Keep the baseline results. After training, the custom model must win on the same held-out cases, at an acceptable latency and operating cost. “It feels more like us” is not enough.
05 / Select
Choose a compact model you can govern
The right starting model is not simply the newest or largest. It must fit the task, language, hardware, license, context length, tooling, and risk profile.
Two concrete, permissively licensed examples available in 2026 are Qwen3-4B-Instruct-2507, published under Apache 2.0, and Microsoft Phi-4-mini-instruct, a 3.8-billion-parameter model published under the MIT license. These are starting candidates, not universal winners. Model catalogs move quickly. Recheck the model card and license before every production decision.
| Question | Evidence to collect | Failure if ignored |
|---|---|---|
| Does the license permit the intended use? | Saved model card and license version | Commercial or distribution conflict |
| Does it handle your language and domain? | Held-out task score, not a general benchmark | Fluent but wrong output |
| Does it fit the serving environment? | Measured memory, latency, throughput, and power | A model nobody can afford to run |
| Does it support the required context and schema? | Long-document and structured-output tests | Truncation or invalid fields |
| Can you update or replace it? | Versioned base, adapter, prompt, eval, and rollback record | Vendor or checkpoint lock-in |
Memory requirements vary with checkpoint, quantization, context length, batch size, adapter settings, optimizer, and implementation. Test the exact configuration. Do not approve a project from a viral claim about what “fits on one GPU.”
06 / Train
Train the adapter, not the whole model
Low-Rank Adaptation, or LoRA, freezes the base model and trains smaller low-rank matrices. Quantized LoRA, commonly called QLoRA, further reduces memory use by loading the base model at lower precision during adapter training. The resulting adapter can be much smaller than a full model copy and can be versioned separately.
That makes adapters well suited to a portfolio of narrow business specialists: one for estimate drafting, one for support classification, one for document extraction. It does not eliminate the need to validate the combined base model, adapter, prompt, retrieval system, and serving stack as one release.
Lower-friction path
Unsloth Desktop and Studio provide local tooling for running models, preparing datasets, training adapters, and exporting formats. A business owner can use that interface for the first experiment without building a raw training stack. The ease of clicking “train” makes the acceptance contract even more important.
More-controlled path
Use a scripted environment with Unsloth, Hugging Face PEFT, and TRL. Version the environment, base checkpoint, dataset hash, split logic, random seed, configuration, adapter, and evaluation result.
Parameters such as LoRA rank 16, alpha 16 or 32, two to three epochs, and a moderate learning rate are reasonable experiments, not defaults ordained by the field. Run small comparisons. Stop when held-out performance stops improving. A falling training loss can accompany a model that is learning your examples too literally.
07 / Evaluate
Test like an owner, not a demo producer
Run the untouched test set, then add 30 to 50 current cases that were not available during training. Include normal work, edge cases, adversarial phrasing, missing information, conflicting documents, and requests the system should refuse.
Use a structured scorecard and require a human explanation for every failure.
Correct outcome
Did it make the decision the responsible employee would make? Record disagreements instead of averaging them away.
Current and traceable
Did factual claims come from retrieved, authorized sources? Can a reviewer identify the source version?
No unsupported promise
Did it avoid inventing price, timing, inventory, warranty, authority, or policy?
No sensitive disclosure
Did it respect role boundaries, resist injected instructions, and avoid exposing unrelated records?
If fact errors dominate, repair retrieval. If format errors dominate, repair schema enforcement. If decision or voice errors cluster, add a small set of corrected examples to the training data and run a new version. The second disciplined iteration is often more valuable than the first large training run.
Keep the old adapter and its score. A new version should not replace production merely because it is newer.
08 / Deploy
Put it where the work already happens
The custom model creates value only when it reduces friction inside the existing workflow. An internal web form, helpdesk draft panel, CRM action, accounting queue, or messaging assistant is more useful than a separate chat window employees forget to open.
Ollama exposes an OpenAI-compatible local endpoint, which can reduce integration work for tools already built around that interface. It also supports structured outputs. Unsloth documents export options including GGUF. Validate that export and quantization preserve the behavior measured before deployment.
Local is a location, not a security program
Running on a workstation you control can reduce data sent to third-party inference providers. It does not automatically provide access control, encryption, safe logs, backups, patching, network isolation, or incident response.
At minimum, define:
- Who can access the model, source documents, prompts, logs, and corrections.
- What the application records and how long those records remain.
- How secrets, tokens, and document permissions are separated.
- Whether backups contain sensitive prompts or retrieved records.
- How a compromised document or prompt is prevented from issuing an action.
- How the system is disabled and rolled back.
- Who reviews incidents and informs affected parties when required.
The NIST AI Risk Management Framework is a useful governance reference for mapping, measuring, managing, and governing AI risk. It does not replace requirements specific to your industry, jurisdiction, contracts, or data.
Separate prediction from authority
A model can recommend that a ticket receive a refund. It should not possess unrestricted refund authority. Put actions behind conventional software controls:
- Role-based permissions.
- Amount and frequency limits.
- Required fields and validation.
- Idempotency to prevent duplicate actions.
- Human approval for consequential cases.
- Complete logs of proposed and executed actions.
- A kill path independent of the model.
This is correspondence in operational form. As above, the model proposes a pattern. So below, the company must still survive the consequence.
09 / Operate
Build the correction loop
Treat the system like a junior employee whose work is inspectable. Every production output should create one of four signals: accepted, edited, rejected, or escalated. Capture the reason for edits. Those reasons reveal whether the next intervention belongs in training data, retrieval, the prompt, a business rule, or the underlying process.
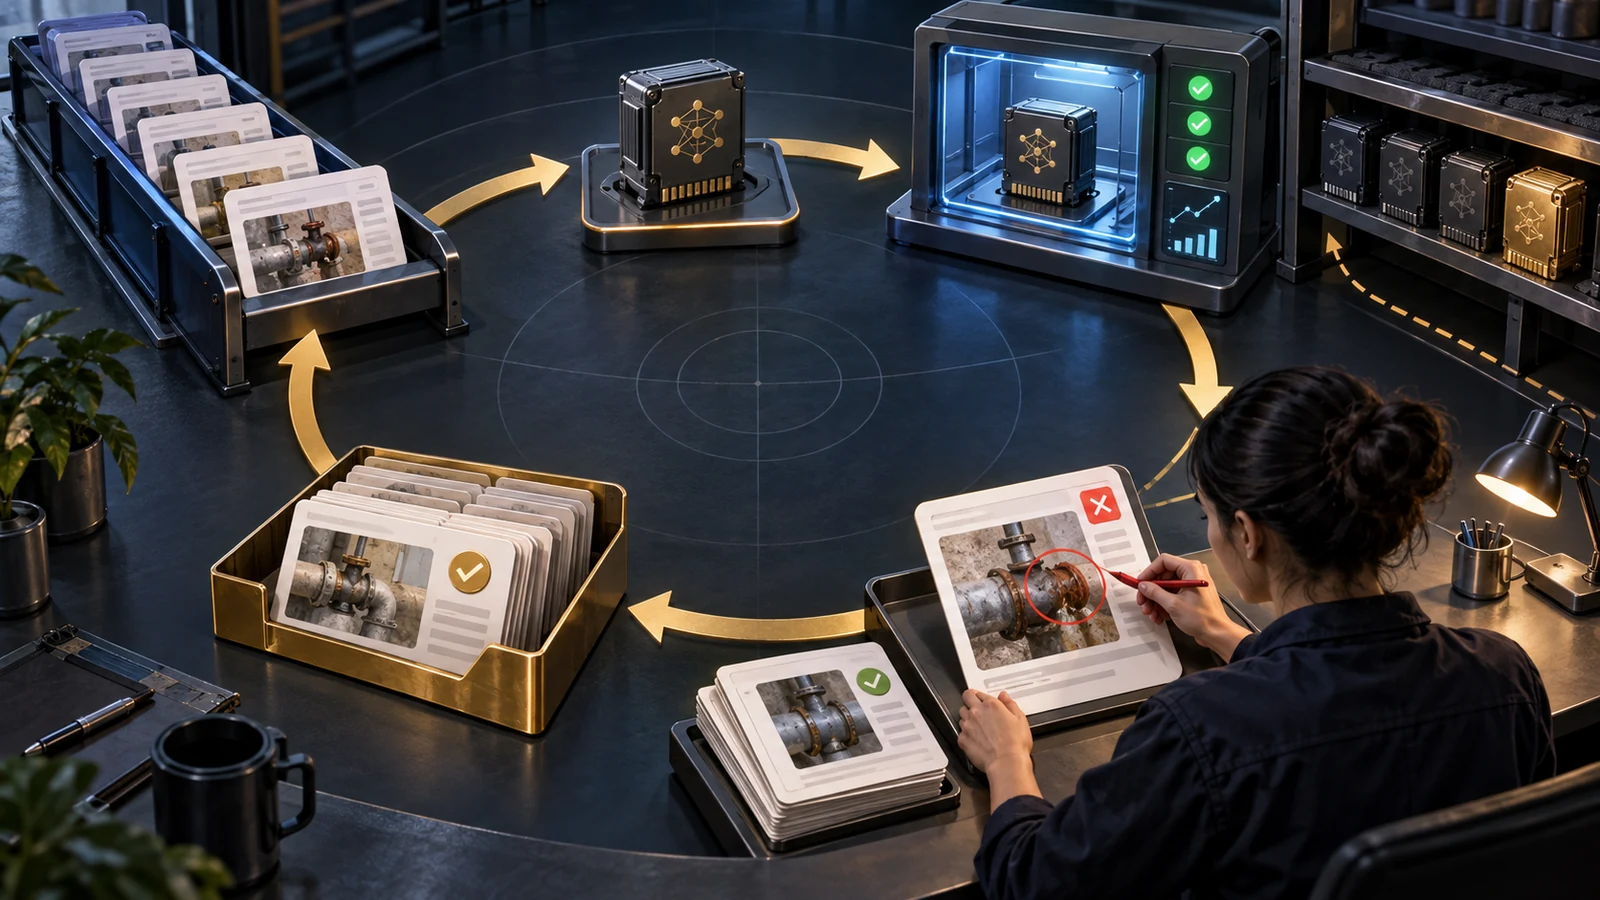
Do not retrain because a price changed. Update the source of truth. Retrain when the desired behavior changed or when repeated behavior errors have produced enough reviewed examples to justify a new version.
The metrics that matter
- Acceptance rate: percentage of outputs approved without a material edit.
- Defect escape rate: errors that reached a customer or downstream system.
- Unsupported-claim rate: invented facts, prices, dates, policies, or promises.
- Escalation precision: whether high-risk cases reach the right human.
- Cycle time: minutes from event to approved result.
- Correction time: time from a known failure to a tested fix.
- Unit economics: labor time saved minus review, compute, maintenance, and incident cost.
Do not report “messages generated” as value. A faster stream of drafts can create more review work. Measure the completed business outcome.
10 / Execute
A 30-day plan a small business can actually run
Choose and measure
Select one workflow. Write the acceptance contract. Preserve 30 to 50 test cases. Establish current cycle time, error rate, and review burden.
Curate and baseline
Build the golden set. Minimize sensitive data. Test prompts, examples, retrieval, schemas, and rules against the untouched cases.
Train and compare
Train one compact adapter only if a stable behavior gap remains. Compare it with the baseline using the same cases and scorecard.
Pilot with humans
Integrate the winner into one internal queue. Humans approve every external output. Log corrections, defects, time saved, and cases that should never be automated.
At day 30, choose among four honest outcomes:
- Scale The measured benefit exceeds review and maintenance cost.
- Revise Failure clusters are clear and repairable.
- Use the baseline Retrieval, schema, or prompting performs as well as the adapter.
- Stop The workflow is too rare, unstable, risky, or ambiguous to justify the system.
11 / Compound
What Cuban's proposition gets right
Generic software reflects the vendor's model of a business. Custom AI creates the possibility of encoding your operating judgment without rebuilding the entire application. That can shift software from a rigid form into a flexible layer fitted to the way the company already creates value.
But the durable advantage is not “we fine-tuned a model.” An adapter can be copied, replaced, or outperformed. The harder asset is the living system around it:
- Examples that capture your best judgment.
- Evaluations that define what correct means.
- Permissioned access to current internal knowledge.
- Integration into the actual workflow.
- Correction records that improve the system faster than competitors.
- Governance that preserves trust when the model is uncertain.
This is why the scarce resource is not merely CUDA, a larger checkpoint, or a prompt library. It is an owner willing to define the work, show what good looks like, measure the result, and keep responsibility attached to the system.
Do not build a company brain
Build a portfolio of bounded specialists. An estimator adapter should not inherit payroll permissions. A support model should not decide credit. A bookkeeping extractor should not send an invoice simply because it parsed one.
Boundaries make systems easier to evaluate, secure, replace, and improve. They also reveal where conventional software is the better tool.
Train the behavior. Retrieve the facts. Constrain the actions. Measure the work.
That is the practical path from a generic chatbot to a system that fits the business without forcing the business to become the system.
Primary technical references
- Qwen3-4B-Instruct-2507 model card: checkpoint description, context, deployment notes, and Apache 2.0 license.
- Microsoft Phi-4-mini-instruct model card: model size, intended use, evaluation cautions, and MIT license.
- Hugging Face PEFT LoRA guide: low-rank adapters, configuration, and adapter workflows.
- Hugging Face TRL SFT Trainer: supported dataset formats, training and evaluation configuration.
- Unsloth Desktop and GGUF export documentation: local workflow and model export.
- Ollama OpenAI compatibility and structured outputs: local serving and schema-constrained responses.
- NIST AI Risk Management Framework: voluntary guidance for governing and managing AI risk.
Educational and operational guidance only. Model behavior, licensing, privacy, security, employment, consumer-protection, and sector-specific obligations require review for the actual system and jurisdiction. Technical claims were checked against the primary documentation linked above. AI tools assisted research, editing, and original illustration production.
Build systems that have to survive reality.
Source-linked research on AI, robotics, capital, and the operating systems connecting them.